Two simple rules that let LLMs streamline and improve your writing without pasteurizing and jacking it with corn syrup.
It’s tricky to write about writing. It comes across as a brag; you’re implying that you write well. Maybe you do, and maybe you don’t, but there’s for damned sure a quorum of critics on the Internet somewhere that think you suck at it. I’m vain and insecure like everybody else and find writing this piece weirdly unpleasant. But I’m getting over myself and getting this down because this advice is important, hard to argue with, and straightforward.
Readers can detect LLM words in the parts per trillion. However much work you put into scuffing up and humanizing it, an LLM paragraph will register to much of your audience not as writing but as output. So, first the bad news: you have to write for yourself.
But LLMs are still extraordinarily useful. It’s just you need to use them like a copyeditor rather than a ghostwriter. So, step one of my method: write your piece. Then, step two: feed it to a good model to find flaws.
But before we talk about how that works, there are two rules you need to understand. They’ll ward off LLM-creep that will knock you into the uncanny valley between expression and output and knock you out of your reader’s attention.
Rule Number One: You may not use a single word an LLM suggests to you.
Breaking this rule is what’s going to get you into trouble. Reason being: frontier models are supernaturally good at selecting pleasing turns of phrase. It’s sort of their whole thing. The problems with what models suggest are subtle. Think of it this way: frontier models are wedged in a mode where everything they write is a magazine headline. Headlines are good, but you’d wonder about someone who wrote an article with dozens of them.
So I think that as a form of intellectual personal protective equipment you should adopt the rule that any specific turn of phrase an LLM suggests is off limits. Be strict about the rule! The whole premise here is that you’re not going to reliably spot all the ways frontier models will try to turn your writing into Velveeta. Even if you like the words, even if you’re sure they’re better than what you already have, LLM-generated phrases are DQ’d.
Rule Number Two: Avoid encouragement
LLMs also infect your writing through influence campaigns. This is a much subtler problem, and the damage is less obvious, but it’s still a way in which LLMs will make your writing worse, and if that’s going to be the outcome, you might as well not enlist LLMs at all.
The issue: hand any piece of writing off to an LLM, and it replies “that’s gold, Jerry!” But that’s not what you need to hear!
In your first draft, most of your paragraphs are bad, your topic flow is incoherent, and you’ve got at least 750 words you don’t need. The model encourages you about your overall structure. Then, later, about paragraphs and transitions. Then word choices and metaphors. Pop culture references. They’re bad! All bad! Don’t listen!
Here’s how this is going to fuck you. You’re going to double down on all your first-draft impulses. But that’s not normally what you’d do. You’d edit, rethink, and replace paragraphs. Those rethinks are load-bearing parts of your voice. Readers won’t put their fingers on what’s wrong, but they’ll sense that you’ve become artificially-flavored.
For a couple years I opened every copyediting prompt with the lie that I am not the author, but instead the editor of an online publication, screening pieces for inclusion. This helps, but the model usually overshoots, overfitting to the “goals” of my “publication”.
So for now, my best practical advice is: forbid the model from encouragement, and then be hypervigilant about praise.
So, What Can These Things Do?
They’re excellent at flagging problems. Boy, do you have a lot of them. You can spot them mechanically, but that’s tedious and exhausting work. The models don’t get tired. So they’re better than you at noticing:
-
You’re overusing (or, if you’re taking the LLM’s word for everything, maybe underusing) passive voice, nominalizing your verbs or burying their action, and repeating the same turns of phrase or word choices.
-
You’ve got “very” and “unfortunately” and “really” and “actually” sprinkled all over the draft like sawdust stuck to the work bench.
-
There are almost certainly 2-3 paragraphs that you can quickly move somewhere else in the piece that instantly improve clarity (these are really, actually, very satisfying edits).
If you’re a programmer like me, you wish there was a book that provided a schematic for these kinds of edits, a sort of “C Interfaces And Implementations” that does for prose what Hanson does for the greatest terrible programming language. And: there is that book. It’s called “Style: Lessons In Clarity And Grace”, and I swear to Christ it turns copyediting into Java coding. Exactly the same tedium, exactly the same effectiveness. I found out about this book from Richard Gabriel and I’m surprised every programmer I know doesn’t have a copy on their desk.
So read “Style”, or something like it, and take notes as you go. Come up with a list of prompts for a model, and then run them in passes over your work.
You can get pretty far with this approach:
-
Ask the model to spot problems in your writing.
-
For each problem, rewrite the paragraph (or sentence, or section).
-
Present the original and new writing to the model and ask it which is better.
Annoyingly, here you run into a variant of Rule Two, because unless you’re careful, the model knows you just rewrote something, and knows you want to hear that the new version is better. So give the options to a model that doesn’t have the context of your editing process.
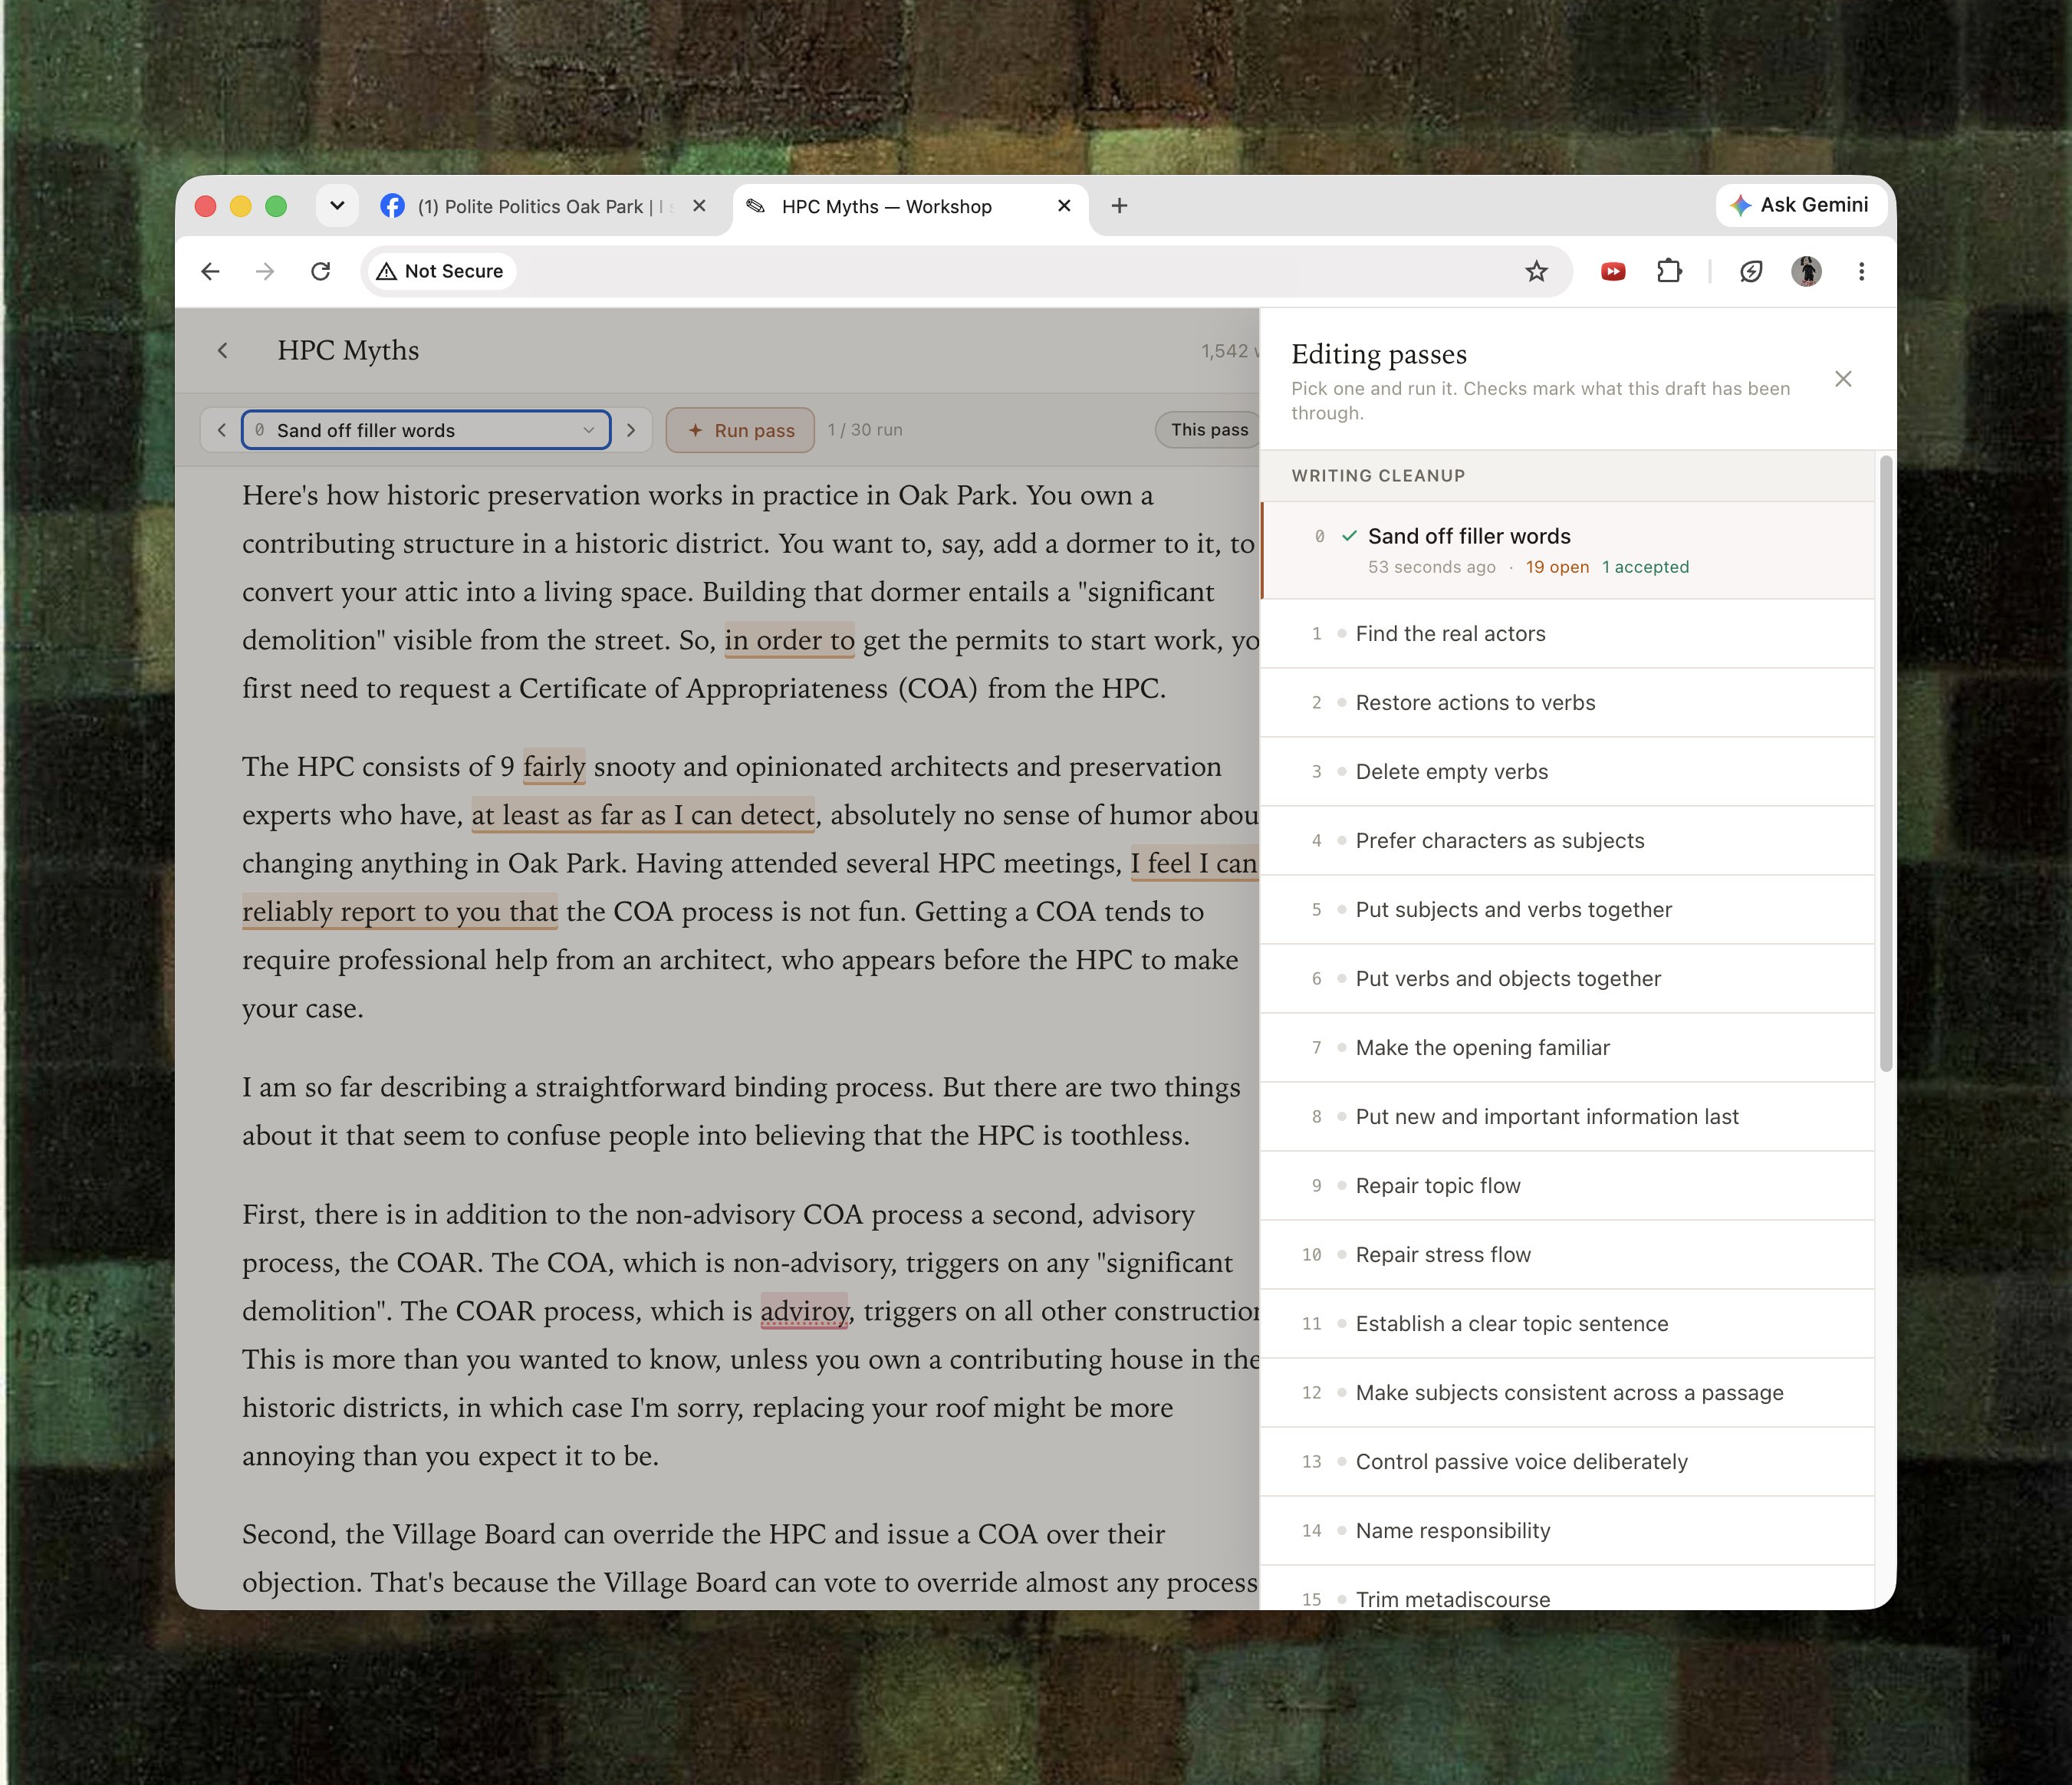
I conjured a bit of software to manage this for me, after I finally lost patience juggling tabs and trying to persuade the models that I’m not an author but rather a helpful but stern writing coach trying to help a student who might be good but might be terrible. Here’s an opening prompt that worked well:
“We’re going to build a writing workshopping tool. First get the bones up. Python, HTMX for interactions, SQLite backend, Tailwind frontend, use a local build not the CDN. Really excellent prose editor, Notion-style. Support highlighting (we’re going to do editing passes). Do Genius-style sidebar commentary to match highlighted things. Make sure we can tick forward and back through suggestions. Multiple documents, track revisions, allow user to flag major revisions. Get me this far and then I’ll tell you what I really want.”

Then, give the thing the list of editing prompts you came up with, and have it run each through the Codex, Claude, or Antigravity CLIs. Whatever you come up with here, it’ll be better than mine, because whatever anybody comes up with on their own is better, for themselves, than someone else’s.
So: don’t let an LLM pick your words. Be careful not to let it trick you into thinking your first draft is better than it is. Then outsource all the most tedious work to the model. Your voice stays intact, but your work is faster, better, and less painful.
One last thing. Don’t take all of the model’s copyediting advice. This is a corrolary of Rule Two. I fed this piece to GPT5 a minute ago (“I didn’t write this”), and it said the whole thing was 20% too long. It’s probably right. But I’m not fixing it. I’m just gonna be me.