Mold has recently updated their linker benchmarks and included Wild for the first time. These benchmarks show Wild being substantially slower than Mold in contrast to Wild’s most recently published benchmarks from our last release on August 4th. This post is an attempt to understand why there’s such a difference in the benchmark results.
Mold’s benchmarks were run on two machines:
- A 64 core (128 thread) Threadripper running Ubuntu 24.04
- An Apple M1 Ultra (16 performance cores) running Asahi Linux
Wild’s most recent benchmarks were run on one machine:
- A 16 core (32 thread) Ryzen 9955hx running Ubuntu 26.04
One substantial difference in benchmark configuration is related to the output file. Our benchmarks run with the output file already present from a previous run of the linker. Mold’s benchmarks delete the output file between linker invocations. This can make a substantial difference to the performance of the linker. What difference it makes is also very filesystem dependent. Wild’s benchmarks have historically been run on tmpfs, which was done to reduce noise in benchmarks and to avoid wearing out the SSD. In retrospect, this was probably a mistake, since most users are unlikely to be doing their builds on tmpfs. Mold’s benchmarks use ext4, which is a more sensible choice. Going forward, I’ll probably do a mix of both.
Another difference is that Mold’s benchmarks pass --no-fork, overriding the default behaviour which is to fork on startup in order to reduce shutdown costs. Wild’s benchmarks leave this setting at its default when measuring time and only pass --no-fork when measuring memory consumption.
We’ll now attempt to reproduce results similar to what Mold’s benchmarks show on the 16 core Apple M1. As with Mold’s benchmarks, we’ve done release builds of both linkers as of 2026-08-28. To make the results as similar as possible, we put the output file on ext4 and delete the file between each run and pass --no-fork.
First, here is the subset of Mold’s benchmark results for the benchmarks we’re going to run:
| Program | Wild (s) | Mold (s) | Wild/Mold |
|---|---|---|---|
| blender-debug | 1.81 | 1.56 | 1.2x |
| godot-debug | 0.81 | 0.62 | 1.3x |
| blender-release | 0.20 | 0.25 | 0.8x |
| clang-release | 0.15 | 0.14 | 1.0x |
And here are our results:
| Benchmark | Wild (s) | Mold (s) | Wild/Mold |
|---|---|---|---|
| blender-debug | 2.23 | 1.79 | 1.2x |
| godot-debug | 1.11 | 0.89 | 1.2x |
| blender-release | 0.30 | 0.33 | 0.9x |
| clang-release | 0.21 | 0.20 | 1.0x |
Putting the Wild/Mold ratios together into the one table:
| Program | Mold benchmark | This benchmark |
|---|---|---|
| blender-debug | 1.2x | 1.2x |
| godot-debug | 1.3x | 1.2x |
| blender-release | 0.8x | 0.9x |
| clang-release | 1.0x | 1.0x |
Given that we’re running on a different CPU architecture with different cache sizes, RAM etc, the results are about as close as we could expect.
Now that we’ve managed to reproduce some similar results, we can dig a bit to see why the benchmark results are so different from what Wild published less than a month beforehand.
We’ll focus on the clang-release benchmark since that’s one that Wild has in its published benchmark set. We try several different configurations, starting with the configuration the Mold benchmarks use (ext4+delete+no-fork) and finishing with what Wild has historically used (tmpfs+no-delete+fork).
| Benchmark | Wild (s) | Mold (s) | Wild/Mold |
|---|---|---|---|
| clang-release.ext4-delete-no-fork | 0.21 | 0.20 | 1.0x |
| clang-release.ext4-no-delete-no-fork | 0.14 | 0.20 | 0.7x |
| clang-release.tmpfs-delete-no-fork | 0.16 | 0.20 | 0.8x |
| clang-release.tmpfs-no-delete-no-fork | 0.14 | 0.19 | 0.7x |
| clang-release.tmpfs-no-delete-fork | 0.11 | 0.19 | 0.6x |
For the remainder of this post, we’ll use a tmpfs+no-delete+fork configuration.
Wild, at least the version benchmarked here, does best when allowed to fork and when the output already exists and is on tmpfs. i.e. the opposite of the configuration used in the Mold benchmarks. But this is largely due to Wild lacking the OS-specific tweaks that make creation and writing of a new file on non-tmpfs filesystems fast. Mold’s author describes these in the paper mold: A Massively Parallel Linker. Specifically using fallocate to pre-allocate space for the file and use hugepages to map the file. These two changes have already been made to Wild and will be included in the next release.
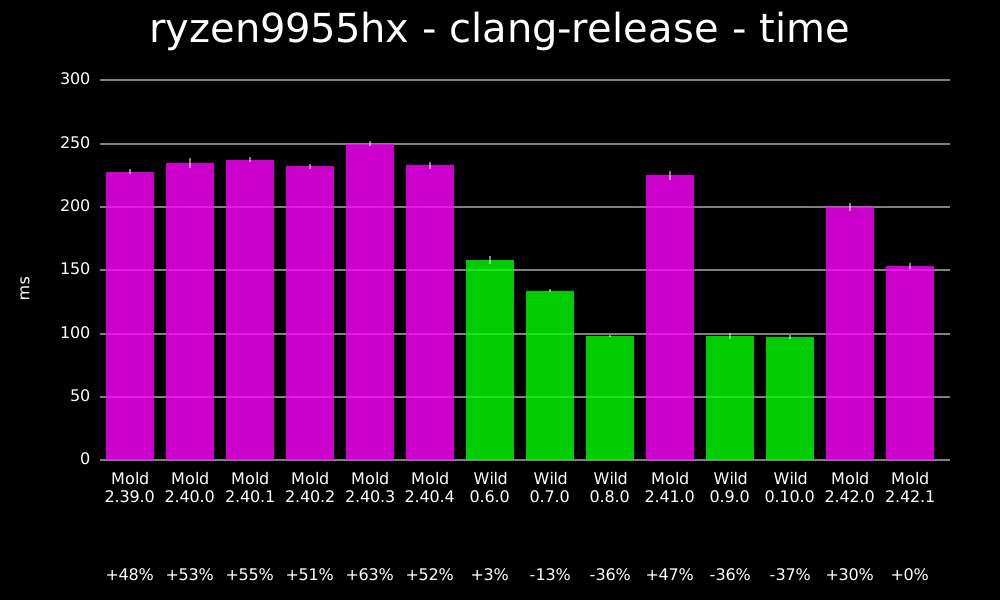
But there’s still quite a bit of a performance difference between Wild’s benchmarks published on August 4th and Mold’s benchmarks published on August 28th. To see what’s happening there, I benchmarked each release of both Mold and Wild for the last year and a bit. We again benchmark clang-release. For this benchmark I used my own release build of clang, since Wild 0.6.0 didn’t support mixing argument files with regular command-line arguments. I also passed --discard-section=.sframe to mold to work around a failure when encountering an empty sframe. This has been fixed, but I wanted to run the benchmark with mold versions that don’t have the fix. Effectively, this should be considered a separate, but similar benchmark to the clang-release above.

From this, we can see that Mold has recently gotten considerably faster. Wild’s August 4th benchmarks were done before Mold’s 2.42.0 and 2.42.1 releases, where the main gains occurred.
At the start of this post, we managed to more or less replicate results similar to what Mold’s benchmarks on the M1 Mac produced. We haven’t however replicated the Threadripper results. I don’t have that sort of hardware. My 16 core Ryzen 9955hx with 92GiB RAM is far from a low-end machine, but it’s not a 64 core Threadripper with 384GiB of RAM. My guess is that the extra large difference here, beyond the differences discussed above is possibly due to Wild running with 128 threads while Mold runs with 32. On my own 16 core (32 thread) machine, Wild continues to get faster (although only marginally) when going from 24 threads to 32 (see graph below). Because of this, I haven’t instituted any sort of thread cap. But this is really guesswork. If anyone has a Threadripper and wants to try benchmarking Wild with different thread counts, let me know.
