Part 1 of a series on how Infino is built.
At Infino, we are building a retrieval engine to answer agent questions at scale, and its full-text search is among the fastest available [1]. Agents query structured, semi-structured and unstructured data, so we need to support SQL, vector search, BM25 full-text search, and any combination across these query shapes. In most cases, the data already resides in the object store, which guarantees scale and high availability. So, we decided to build the search index on the object store, supporting S3, GCS and Azure Blob Storage.
Search engines have traditionally kept their index on local disk. Lucene, which most search engines are built on or modeled after, assumes the index sits on a disk next to the CPU, where a random seek is relatively cheap. However, that is not the case when you move the index to object storage, where every random read is a network round-trip. In this post, we describe some of the design decisions we made differently because of that.
Architecture

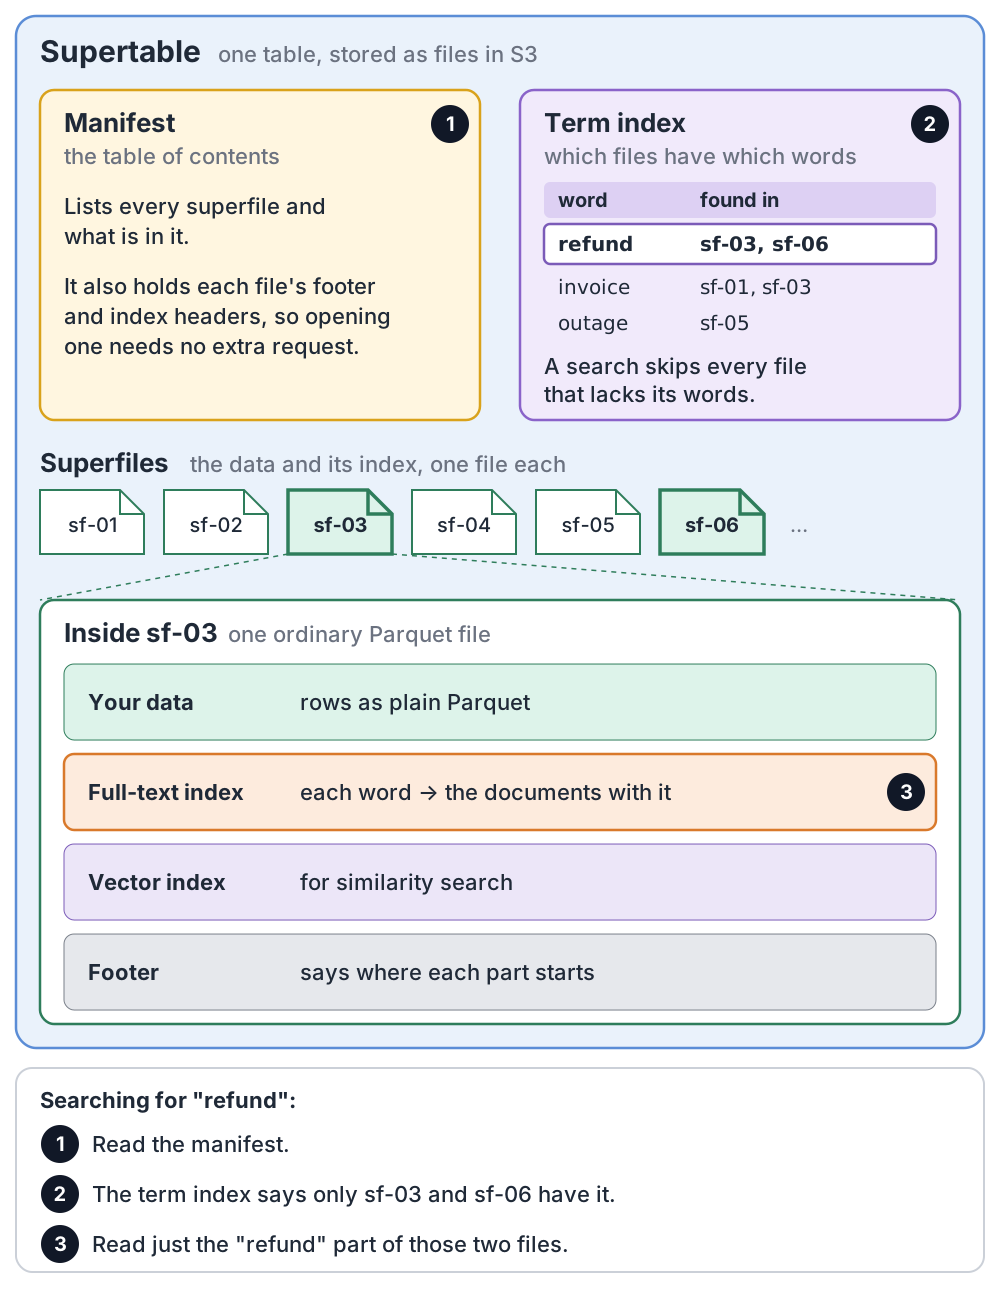
Infino organizes the data into superfiles, which are Parquet files with Infino’s full-text and vector indexes. Many superfiles form a supertable. Each supertable has (a) a manifest, which lists superfiles along with their footers and index headers plus column statistics, and (b) a term index, which lists terms along with which superfiles they appear in and score bound information.
The cost model
On a local SSD, a random read costs nothing if a page is cached, and costs under a millisecond in case of a page fault. So a search engine whose index is on SSD can afford to make random reads liberally. On S3, GCS or Azure Blob, every random read is an HTTP GET request, which typically takes tens of milliseconds, and is billed in $$ per request, regardless of how many bytes it returns. This changes what you need to optimize when building a search engine on object storage. The scarcest resource is not CPU, and not bytes, but the number of round trips you make to the object store, and most design decisions below follow from that [2].
One file per index unit
Search indexes are built as immutable units. You ingest a batch of documents, and the engine writes a self-contained index for them. Updates are written as new units too, and a background merge process later combines old units into new immutable units. In Lucene, the immutable unit is called a segment; in Infino, it is called a superfile. The index data structures Infino uses are the topic of a later post, but a curious reader can read about them here: superfile architecture.
A Lucene segment is a set of files: a term dictionary (.tim), an index into the term dictionary (.tip), postings (.doc), positions (.pos), and so on. By default Lucene packs small segments into a compound file (.cfs, with an entry table in .cfe), while large segments keep their separate files. Either way, opening a segment on object storage takes several GET requests.
An Infino superfile is always a single object: a plain Parquet file. The documents are ordinary row groups, and the full-text and vector indexes are spliced in as byte regions just before the Parquet footer, located by keys in the footer’s metadata. DuckDB or PyArrow or any other Parquet reader can read this file as a normal Parquet file. Because each section’s byte offsets are recorded in the metadata, any section of a superfile can be fetched with a single ranged GET.
The manifest
Each supertable has a manifest, which lists the superfiles that make up the supertable. A write creates new superfiles, writes a new manifest that includes them, and then atomically swaps a small pointer file to the new manifest, so readers always see a consistent set of superfiles.
The byte offsets of the full-text and vector indexes are stored in the Parquet footer, i.e. at the end of the superfile. The full-text index also has a small header that a reader needs before it can look up any term. If a query reads these from every superfile, it would cost an extra GET per superfile before any search work even starts. So, the manifest stores the Parquet footer and index headers of every superfile inline. The manifest is usually cached, and since it already holds the Parquet footer and the index headers, opening a superfile needs no GET at all. The first GET a query makes to a superfile fetches data it actually needs, such as postings of a term. This reduces the cold cost of each superfile from two round trips to one.
The manifest also stores column statistics for every superfile, such min, max, and null count of each column. A query with a filter like created_at > '2026-10-01' can skip a superfile whose max created_at is older than that, without opening it. However, column statistics can’t tell whether a superfile contains the word “refund”, which is what the term index described in the next section is for.
The term index
Without a term index, a full-text query has to ask every superfile whether it contains the query’s terms. That requires reading each superfile’s term dictionary, which means at least one GET per superfile, even for superfiles that turn out not to have the term at all. A supertable can have thousands of superfiles, so this gets expensive quickly.
So, each supertable also has a term index, which lists every term along with the superfiles it appears in. For each term and superfile, it stores (a) the number of documents in that superfile that contain the term, (b) a score bound, i.e. the highest BM25 score the term can give any document in that superfile, and (c) the byte offset of the term’s postings inside the superfile. The term index is split into slices by term range, so a query fetches only the slices that hold its terms, not the whole index.

With this, a query for “refund” first looks up “refund” in the term index, and finds that only sf-03 and sf-06 contain it. It skips every other superfile without opening it. Since the term index also has the byte offset of the postings, the query fetches the postings for “refund” from sf-03 and sf-06 with one ranged GET each, without reading their term dictionaries.
The document counts and score bounds help as well. For a top-k query, the query visits superfiles in descending order of score bound, and skips a superfile once its score bound is lower than the k-th best score found so far. A count query for a single term can be answered from the document counts alone, without opening any superfile [3]. In one of our tests, a single-term count on a supertable with 141 superfiles went from opening 141 superfiles to opening none. The same document counts also give BM25 the corpus-wide statistics it needs for scoring.
The term index is kept up to date on every commit: a commit that adds superfiles also appends their terms to the term index, and a background optimize step periodically merges these additions into one compact index.
Read only what you need
A superfile can be over a gigabyte, and a query usually needs only a small part of it. So, Infino reads a superfile lazily, by byte range.
When a query needs a term, it fetches only the postings of that term. The document lengths, which BM25 needs for scoring, are fetched only when a query computes scores, so a count query never reads them. Positions are stored in their own region, and are fetched only when a phrase query needs to check word order.
When a query needs postings of several terms that are close to each other in the file, Infino fetches them in one request, as long as the gaps between them are small (up to 64 KB), since reading a few extra bytes is cheaper than making another round trip. Bytes that a query has already fetched are reused within the query, so that nothing is fetched twice.
Caching on disk and in memory
Even a few GETs are slower than reading from a local disk. So, Infino also caches superfiles on local disk. When a query touches a superfile for the first time, it reads the byte ranges it needs directly from object storage, while Infino downloads the full superfile to local disk in the background [4]. Once the download finishes, the superfile is memory-mapped, and subsequent queries on it make no GETs at all. The disk cache has a size budget (10 GB by default, but configurable to the size of the local disk), and the least recently used superfiles are evicted when it is full.
Caching in memory comes from the memory map: the operating system keeps frequently read pages of the superfile in RAM, and Infino releases the pages of superfiles that have not been queried recently. The manifest and the term index are aggressively cached as well, as they are typically read by every query.
Conclusion
Moving the search index to object storage changes what you need to optimize. On local disk, a random read is almost free, but on object storage, every random read is a GET that costs tens of milliseconds and is billed per request. So, most of Infino’s design is about making fewer round trips. A superfile is a single object, so a query never has to open many files for one index unit. The manifest holds the footer and index headers of every superfile, so opening a superfile needs no GET. The term index tells a query which superfiles contain its terms, so it skips the rest. A query reads only the byte ranges it needs, and the disk and memory cache means a repeated query often makes no GETs at all.
However, the core of the search engine did not change. Postings lists, BM25 scoring, block-max pruning and the query algorithms are the same ideas Lucene uses, and in several places Infino builds directly on ideas that Lucene pioneered. What changed is the storage layer, because that is where the cost model changed.
In the next posts, we will go into the index data structures inside a superfile, and how Infino runs a query across many superfiles in parallel.
If you have reached this far, please consider giving our open source repo (infino-ai/infino) a star on GitHub.