Zooming in on the models split specifically:
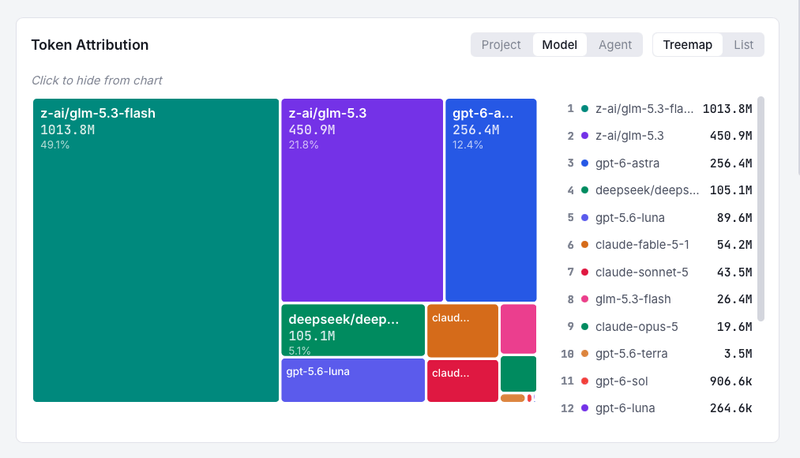
The goal was to spend the whole month on GLM 5.3 Flash pictured in teal. Here’s what went well:
- Successfully spent the first half of the month on just that model.
- That model’s usage was well within our budget ($68, about 4kWh of energy use / 365 grams of carbon emissions).
The second half of the month didn’t go so well, with 1B tokens going to other models.
Unexpected hurdles
The cost of vibe coding
We’re pretty transparent that our experimental Wagtail MCP server is a vibe-coded prototype. Vibe coding isn’t quite what we normally aspire to, but for a prototype it’s spot on. Unfortunately there are still consequences to it. I chose the 'wrong' model for the prototype, and we spent 450M tokens / $150 / 5kWh of energy use almost overnight. The MCP server itself works well and we now have a great demo of the capabilities, so it’s not for nothing:
Nonetheless, it’s a good reminder to be careful with model selection and with agentic patterns. We could have achieved similar results for most likely 5x less cost with not that much more effort. Lessons learned! We need to budget for this, and be more careful. Could have seen it coming, but now we know.
Infrastructure woes
Another unexpected hurdle was infrastructure availability issues. We’ve written extensively about comparing inference providers. Our choices work really most of the times, but it turns out they’re very popular, and do not have the same capacity as the big labs who hoard all the GPUs. We noted degradation with the performance of GLM 5.3 Flash in particular, most likely because of it being so high up the Pareto frontier of relevant models for our work.
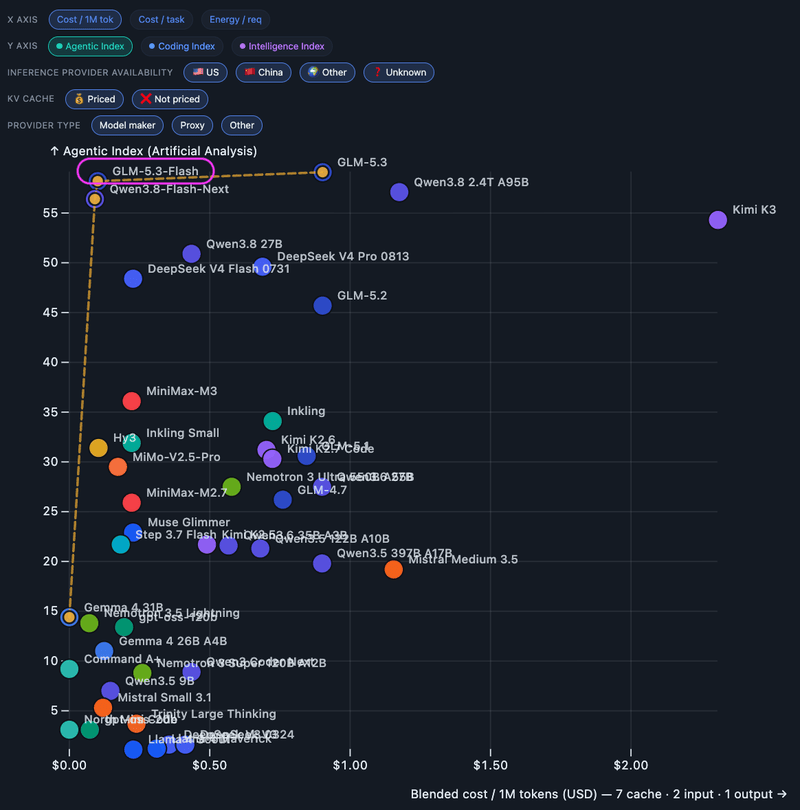
This meant having to switch to other similar models (DeepSeek V4.1 Flash, Qwen 3.8 Flash). Which is very simple to do, but nonetheless unexpected!
The cost of experimentation and R&D
Last but not least, beyond using one model for day-to-day engineering, it felt essential to keep experimenting with a wide range of models, keeping up with what providers are releasing. This is particularly essential as we start to benchmark models’ performance on Wagtail tasks, where we need data across a wide range of models. Sneak peek of our benchmark:
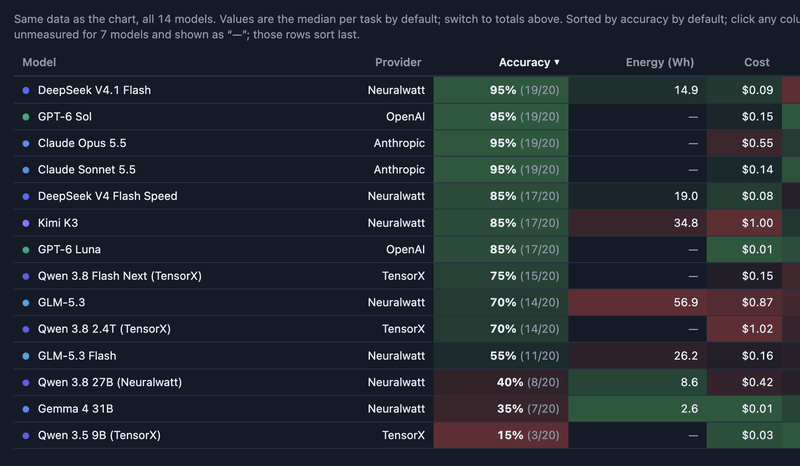
It’s much easier to guide people towards leaner options with this kind of concrete data. And for us to make those options even more viable with agent skills, or our new CLI prototype, which is intended to work well with agents.
Takeways and what to do next
So technically this challenge was a failure. Only 50% usage on the target model, 1B out of 2B tokens. About 35 kWh of energy use instead of 10. But we did learn a lot, which is crucial for the current moment. Reflecting on this for October, here’s what will make it work:
- Constant, local usage measurement and reporting. Looking not just at tokens but also energy use and spend, and ideally how well this all leads to concrete positive outcomes.
- Budgeting for experimentation, not just day-to-day tasks. Making more concerted decisions about which prototypes are worth building, and how.
- Better prompt selection and multi-agent techniques. Orchestrator vs. scout vs. implementer vs. reviewer agents. Bounded goals. Not rocket science but certainly one more thing to learn.
- Keep pushing for more efficient techniques and models. The Jev-style decision diffusion models look very promising if they can run so efficiently. Latest flagship models also look like a step in the right direction on that front.
For day-to-day developer work, it’s totally viable to focus on one or two flash-tier cheap models. A viable target is probably that the majority of AI inference work should be done with such efficient models, measured in cost or energy use rather than meaningless tokens. That’s the goal for October! You should try it too, you’ll learn a lot in the process.
And come say hi at Wagtail Space 2026 in November to hear how that all pans out!