Note: as always, all my public writing is written by hand by me.
Overview
A bloom filter is a probabilistic data structure that allows you to quickly and cheaply answer the question "is key X in this set?" with either "definitely not" or "probably".
You pick a false positive rate that is acceptable for your workload and hardware, add keys to the set, and check for their existence later on.
Bloom filters use a small amount of memory compared to the cardinality of the set, and are computationally very cheap. For these reasons, they're frequently used in high performance data systems.
For example, a database might keep an in-memory bloom filter and check it before actually going to disk when looking up rows. This saves substantial amounts of very slow disk IO.
We also use them all over the place in the Bluesky backend. They allow us to save millions of queries per second against our Scylla database when looking up blocks, mutes, labels, and more. For instance, we can often answer the question "does user X block user Y" without even hitting the database.
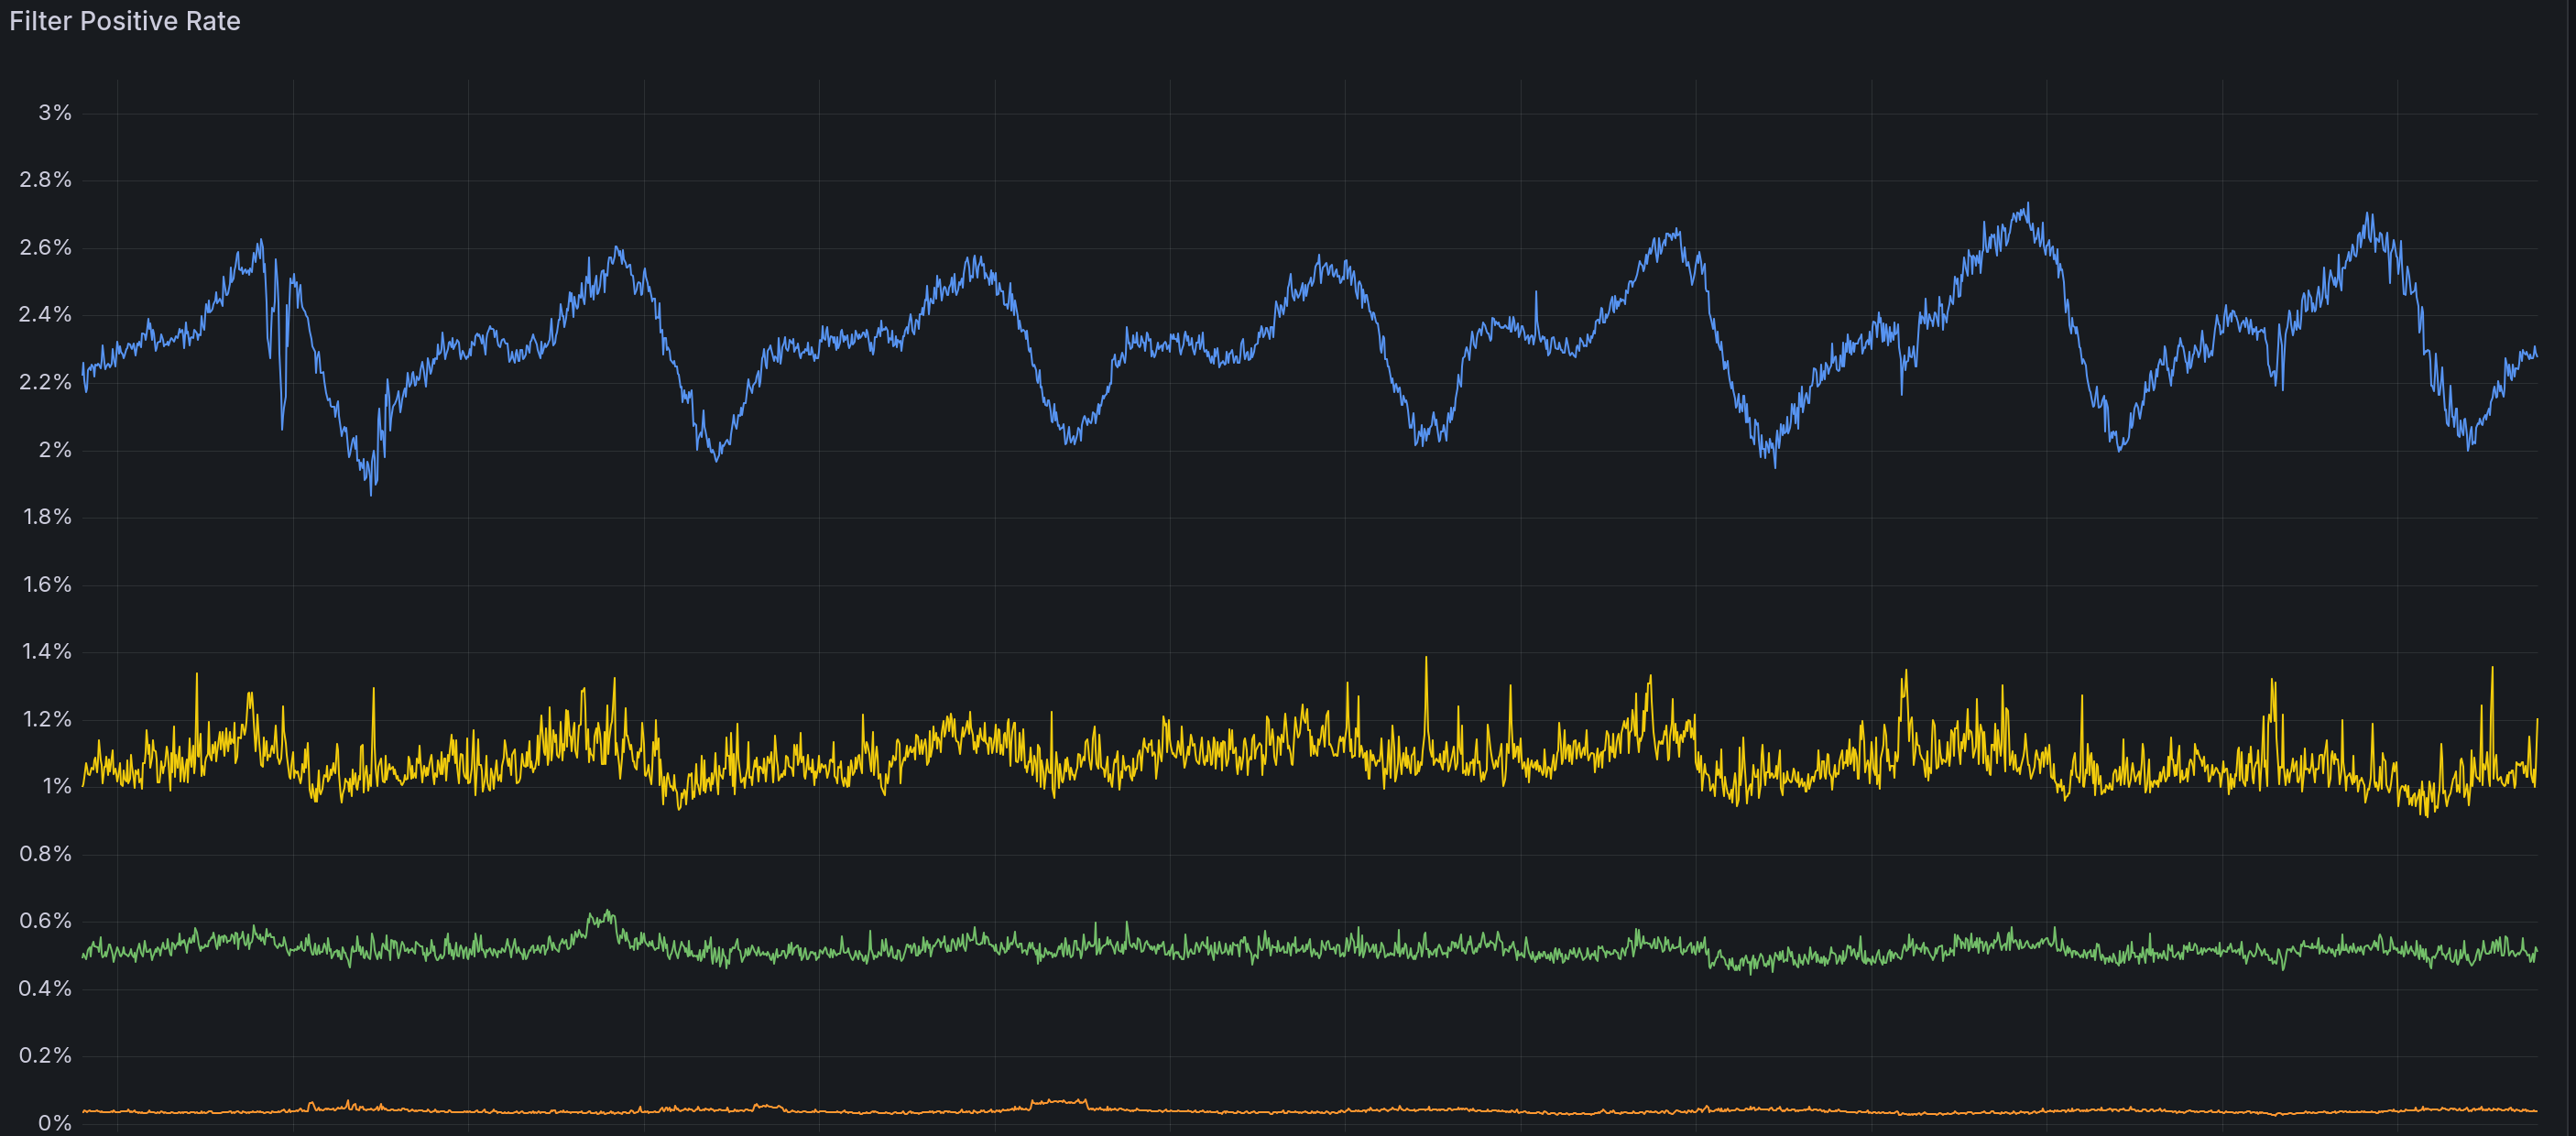
Here's the last several days of some of our bloom filter positive hit rates:

The above yellow line has a roughly 1% positive rate, which means that 99% of the time, we can completely skip querying our database. This has been critical in our ability to scale the site and operate the site cheaply.
Traditional Bloom Filters
A bloom filter is an array of bits and k hash functions. You choose the size of the array and k before hand, and want to right-size it to your workload to achieve a specific false positive rate.
To add a key to the set, run it through the k hash functions and set the bits at each of those locations.
To check if a a key is in the set, hash it k times and check each resulting location in the bit array. If any bits are zero, the key was never added. If all bits are set to one, it might be in the set.
Here's an example of a potential positive:

And a definite negative:

Pretty simple!
Double Hashing
While much cheaper than going to disk, computing k independent hashes per key is still a bit expensive for very high performance systems.
In 2008, Kirsch and Mitzenmacher wrote a paper demonstrating that two hashes can get you the same output. The math is far over my head, but if you derive the i-th location as (hash_1 + i*hash_2) % n, then the false positive rate is effectively the same as using k independent hashes. Phew!
bits-and-blooms/bloom maintained by Daniel Lemire (a huge inspiration of mine, you should buy his book) is a fantastic double hash bloom filter implementation written in go. It runs 128-bit murmur3 twice to get four 64-bit values, then combines them to produce all k bit locations. We used this in production at Bluesky for a long time.
For the Bluesky backend, we essentially do a SELECT * FROM blocks, mutes, list items, etc. every time one the processes starts, and add all the items to the bloom filter. There's also a real time atproto firehose consumer inserting items in to bloom filters (even during process startup), so there is a race condition if you're not careful.
The problem with the bits-and-blooms library is that it's not internally thread-safe, so we needed to wrap all bloom filter access in a mutex lest we suffer a data race. pprof showed that mutex contention was actually the bottleneck in launching the process. A single deploy used to take 90 minutes to roll out fully because of this!
So my colleague Jasmine forked the library and created atomic-bloom, which uses atomic CPU instructions to do the same logic, but safely and without mutexes. This led to substantially less contention and was massively faster than the mutex-based approach. Our deploys dropped from 90 minutes to about 15, which enabled us to ship faster and with greater confidence. Awesome!
One Hash
Can we go further?
For Bluesky, the answer is no. Contention was our original problem, not the number of hash functions or other factors, thus by Amdahl's Law we did not receive any further speedup resulting in a noticeable impact. However, it's still fun to go deeper and learn something new!
As part of our research on bloom filter techniques, we came across this paper from Lu et al. that uses even more math to show how to do bloom filters using only a single hash.
Here's an overview of how it works:
- Instead of one big bit array, split that into k array partitions of fixed sizes
- Each partition has a different size, and all the sizes are pairwise coprime, meaning that no two sizes share a common factor other than one
- You hash the given key once to get hash
- The bit position in partition p is
hash%size_p(the size of the partition) - Since you have k partitions, you get k bit positions to check out of that single hash
- You can use those k bit positions as you would with other bloom filter types!
With this technique in hand, I made jcalabro/gloom, a one-hash bloom filter (OHBF) implementation in go. This has been live in the Bluesky backend for the past 9 months and has been holding up quite well. It's also used in jetstream, our high performance sync service.
Here's an example of how it's used:
package main

import (
    "fmt"
    "sync"

    "github.com/jcalabro/gloom"
)

func main() {
    // Create a thread-safe atomic bloom filter with:
    //    - Expected capacity of 1 million items
    //    - Approximate false positive rate of 1%
    f := gloom.NewAtomic(1_000_000, 0.01)

    var wg sync.WaitGroup
    defer wg.Wait()

    for i := range 8 {
        wg.Go(func() {
            for j := range 100000 {
                str := fmt.Sprintf("key-%d-%d", i, j)

                if f.TestString(str) {
                    // always a false positive since the key isn't in the set
                    fmt.Printf("found a false positive: %s\n", str)
                }

                f.AddString(str)
            }
        })
    }
}
Now, let's step through how it works under the hood in more detail. Here's some sample go code that shows how we select the block index as well as h for a given key we want to check:
hash := xxh3.Hash128(key) // calculate the 128-bit hash

block := hash.Hi % numBlocks // high 64 bits pick the block
h := hash.Lo                 // low 64 bits are the hash we'll check
Then, you check your bloom filter as follows:

In addition to being a single hash, it also does some fun performance optimization techniques.
First, we split the bloom filter into many 64-byte blocks to match common CPU cache line size. Next, since go's allocator doesn't ensure that those block allocations are cache aligned, we slightly over-allocate and use unsafe to ensure alignment. See here for the implementation.
These two techniques combined guarantee that in the worst case, a bloom filter lookup only takes one cache miss. Nice!
There's another fun optimization from Daniel Lemire that allows you to select which block to check with a single MUL instruction rather than modulo, which requires an expensive division instruction.
The final interesting optimization I'll talk about is the ShardedAtomicFilter. At Bluesky, I managed a large fleet of top of the line bare metal servers. In order to eke the most performance out of those systems, it's good to avoid having multiple cores fight over the same data. ShardedAtomicFilter spreads writes over many backing filter shards, which reduces the likelihood of contention.
Conclusion
Bloom filters (and roaring bitmaps) make the world go around.
Hopefully this was an interesting little exploration in to how they work. If you're interested in fun low-level engineering details, consider following me on Bluesky or subscribing to this blog via atproto, RSS or similar.
Side note: I've been working on a novel observability suite that pushes the state of the art. Star it on github and keep an eye out for more discussion in the near future!