I can't believe it's not silicon
Qwenputer is a pretty fun experimental model. It's a stock Qwen 3.5 4B with one addition: a RISC-V CPU embedded within the weights that uses the model's own Gated DeltaNet attention layers as RAM. (To learn how GDN works, here's a handy guide.) This 'CPU' runs completely within the forward passes of the model, and can run arithmetic operations, C and MicroPython code without any external runtime or tool usage whatsoever.
To be very clear, it is not a plugin, a tool or a sandbox. This blog will explain exactly how this model works, and how the model utilises GDN layers as RAM, and how I also slotted in an experimental in-model file storage.
I also wrote up two follow-ups built on top of Qwenputer: how hybrid models can learn to hide their reasoning in their RNN state and evade CoT monitoring, and how compiled weights like these can work as inbuilt monitoring tools that the model itself can't tamper with.

You can grab Qwenputer from Hugging Face or ModelScope, and the code is on GitHub.
The RNN inside Qwen3.5 can be exact RAM
Qwen3-Next and Qwen 3.5 (the model Qwenputer is built on) use a pretty neat trick. 3 out of 4 attention layers in the model use Gated DeltaNet, a linear RNN, as the attention mechanism (more on that here). Each head keeps a state matrix, and the delta rule keeps this updated.
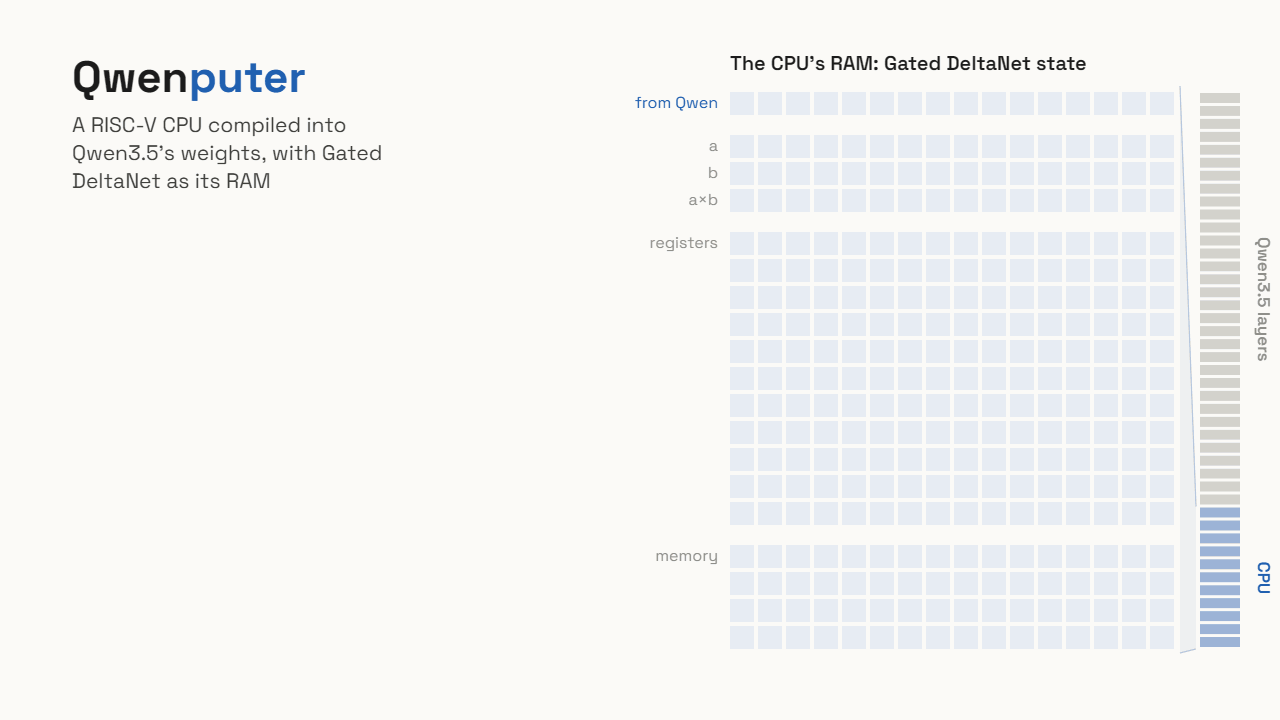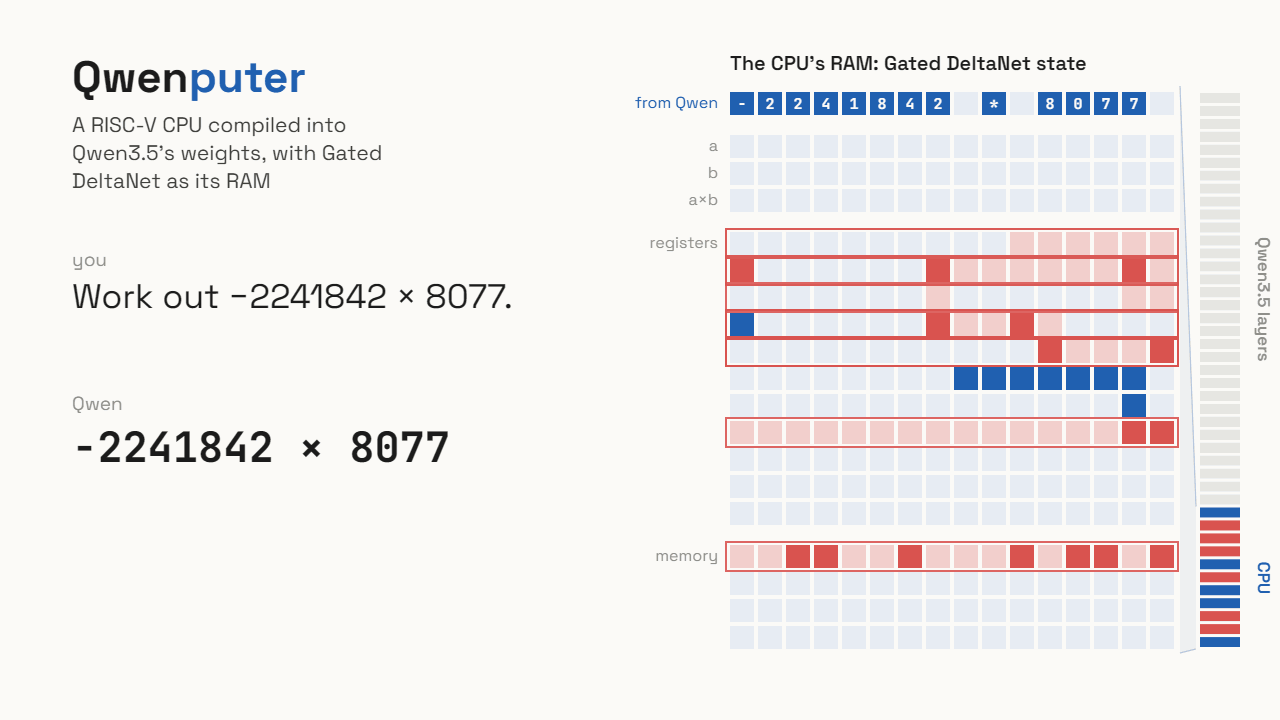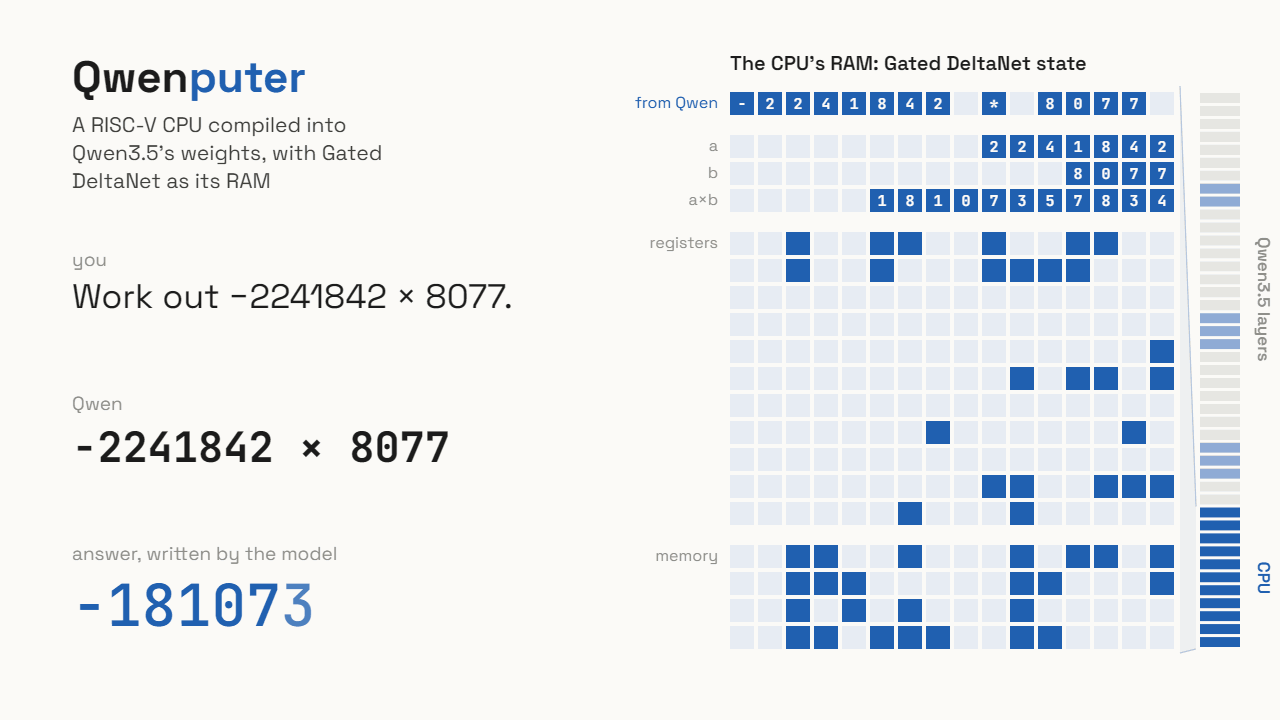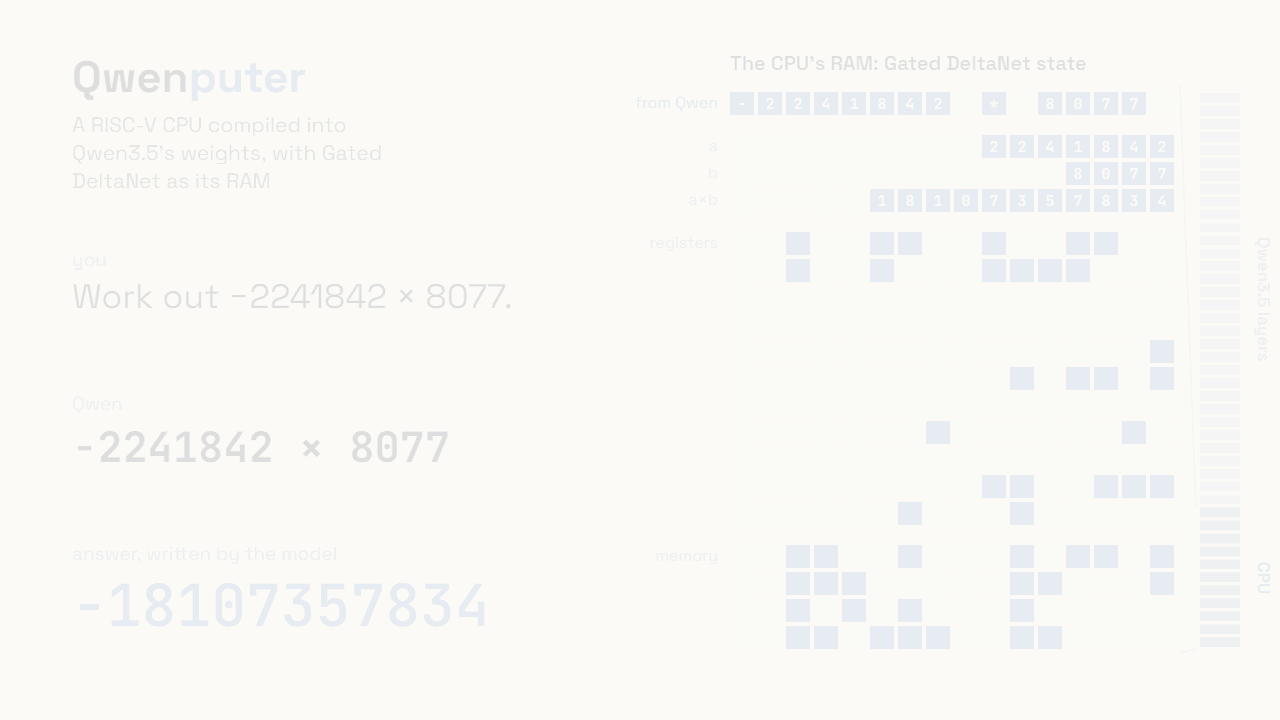
Now, here's where our fun experiment starts. I found out that by setting the gate to 1,1 Each Gated DeltaNet head keeps a state matrix, its memory. At every token, before writing anything new, it multiplies the whole state by the gate, a number between 0 and 1. That's how the RNN forgets: a gate of 0.9 fades everything stored a little on every token, and a gate of 1 means nothing ever fades. the write strength (beta) to 1,2 After the gate, the head nudges one direction of the state towards a new value, and the write strength beta sets how far. A beta of 1 means the old value along that direction is replaced completely instead of blended. and using one-hot key encoding,3 A one-hot key is a vector of zeros with a single 1 in it, so it points at exactly one row of the state, the way a memory address points at one cell. every write we perform will overwrite exactly one row, and every one-hot query can retrieve an exact value. This means that the GDN layers themselves can work exactly as RAM, at a far lower cost than using normal attention as RAM, since a GDN head's state stays the same size however long the conversation gets, unlike attention's KV cache.

The idea that the delta rule acts as a memory isn't new: Schlag et al. (2021) showed that linear attention with the delta rule works as an associative memory, or "fast weights".4 Imanol Schlag, Kazuki Irie and Jürgen Schmidhuber, "Linear Transformers Are Secretly Fast Weight Programmers", ICML 2021. The new thing here is making it exact and addressable, inside a production model, reliably enough to run a whole CPU on it.
This is the base on which this entire model is built. As it stands, default Qwen 3.5 does not keep exact values in the GDN. With this modification, we unlock the next part of this experiment.
Compiling a computer into layers
Since we have a fully functional, cheap and fast RAM now, we can go ahead with compiling a working CPU into the model weights. Luckily, there's no training involved: a compiler sets every weight directly. You describe the CPU as a circuit, a long list of small steps like "read this register", "add these two numbers" or "jump if zero", and the compiler turns each step into a piece of a transformer layer: attention heads that look things up, feed-forward units that do the arithmetic, and DeltaNet heads that hold the RAM. The CPU then runs as the model decodes.
Each instruction becomes a few generated tokens: one names the memory row to write (ADDR), the next carries the value (VAL), and a STEP token ends the instruction. Those tokens are the CPU's execution trace, so while Qwen is generating them, the CPU is actually running.
The CPU
The CPU is a 32-bit RISC-V core (RV32IM, plus the Zba extension and a small bignum unit for big-number arithmetic), and it takes up 11 layers in front of Qwen's 32. As it stands, it passes the official riscv-tests, its programs match qemu, and it has run 18 million instructions free-running without a single error.5 Free-running means the CPU keeps going on its own outputs for the whole run, with no reference machine correcting it between steps.
This CPU can also run C and MicroPython code in the forward passes quite well (although a bit slowly). It is not a Linux-class chip yet, but it implements the full RV32IM instruction set.
How Qwen uses it
Qwen 3.5 4B is able to use this CPU quite well, without any post-training required. The CPU is used completely internally, and not invoked through any external tool calls.
In order to make the model use this reliably, I decided to go the cheap way: by piggybacking on the tool call format that models are quite well-trained on, Qwen sends the CPU its instructions and reads back the results. No external tool calls or runtime are used. Once our CPU receives the instructions, the computer layers run, and then write the tool response. We use a small driver called RvChat to load the firmware into the GDN state, and this keeps the trace tokens out of Qwen's layers.
Qwen's original weights stay exactly as they are. The computer weights are added on top of them, in extra dims and layers.
Does it work?
I think the main question here on your mind after reading through my incessant ranting will be: does this actually work?

On the DeepMind sets:
- div_big: Qwenputer scores 97.5%, versus 95% by giving Qwen 3.5 4B a Python tool and 72.5% for base Qwen.
- mul_big: Qwenputer scores 97.5%, versus 100% with a Python tool and 55% for base Qwen.
- mul_div_multiple_longer: Qwenputer scores 100%, versus 97.5% with a Python tool and 90% for base Qwen.
- add_or_sub_big: Qwenputer scores 97.5%, the same as with a Python tool, and 87.5% for base Qwen.
On NUPA's long-integer arithmetic, Qwenputer goes from 48.6% to 100%, the same as giving Qwen a Python tool.
The numbers the CPU prints are exact, too: I replayed about 230,000 of its output positions against a reference machine and found zero mismatches. And bolting a computer onto Qwen doesn't change how it talks: its normal text stays within noise of base Qwen (KL 6e-4, against a noise floor of 5e-4).
A hard drive? In this economy?
Because a CPU inside a language model clearly wasn't cursed enough, I decided the prudent thing would be to give it a filesystem too.
Since we already have a functional RAM, this was mostly trivial. On the model side, it's exposed via internal put / append / get / list / delete operations. Once again, no actual tool calls. When Qwen 'saves' a file, the compiled layers hash its name into one of 1,024 slots in a directory kept in the DeltaNet state, and store the text itself in other heads, with eight tokens per row, chained together. In scenarios where two names end up landing on the same slot, it just checks the next one. Finding a file again takes roughly two or three steps instead of a scan, and it holds up to 512 files, which comes out to about 53,000 tokens of text.
Fun thing is, this is quite persistent. You can save the state at the end of a conversation, load it into the next one, and the files are still there. Using this filesystem, Qwen gets facts that changed between chats right 90% of the time, against 30% when you paste the old chats back in, and it's on par with giving Qwen memory tools run by Python (83.3% vs 78.9%). This one is still experimental, and its code lives on the rv-store branch, with the model on Hugging Face and ModelScope.
Limits and what's next
Qwenputer is very much an experiment, so a few limitations. The extra layers and wider hidden size make the checkpoint 18.8 GB, roughly double base Qwen, although most of it is zero padding. It also needs a small driver (RvChat) to boot the firmware and keep the trace tokens out of Qwen's layers, so it doesn't run with a plain generate() call yet. And it's a bit slow, with every CPU instruction costing a few decoded tokens, so a big calculation takes seconds rather than milliseconds. The batched executor I used for the benchmarks runs about 3,200 CPU tokens a second on an L4.
Next up, I want Qwen to write Python and run it on the MicroPython inside its own weights, through a python() tool that works the same way calc does. Making the CPU faster is the other big one.
Beyond arithmetic
Exact control over the RNN layers is useful for a lot more than arithmetic. It also makes Qwenputer a really nice testbed for AI safety research, and I wrote up two follow-ups: how hybrid models like Qwen 3.5 can learn to hide their reasoning in their RNN state and evade CoT monitoring, and how compiled weights can work as monitorability tools, like an in-weight monitor the model can't switch off, or answer keys for interpretability.
Try it
If you want to play with it yourself, the model runs on a single 24 GB GPU. You'll need uv and the Hugging Face CLI. You don't need a tool server or a Python sandbox for the calculations: the CPU runs them inside the model.
git clone https://github.com/divagr18/qwenputer && cd qwenputer/experimental/riscv && uv sync --extra hf
hf download divagr1925/Qwen3.5-4B-Qwenputer --local-dir qwenputer-rv
uv run python -m chipformer.rv.chat qwenputer-rv --firmware tests/data/rv/calc-bridge.elf \
    --ask "Use calc: what is 123456789 * 987654321?"
Everything is open: the code on GitHub, and both models on Hugging Face (Qwenputer, Filesystem) and ModelScope (Qwenputer, Filesystem).
If you use it in your work, you can cite it as:
@software{agrawal2026qwenputer,
  author  = {Agrawal, Divyansh},
  title   = {{Qwenputer}: a computer compiled into the weights of a pretrained language model},
  year    = {2026},
  url     = {https://github.com/divagr18/qwenputer}
}